Class anira::LiteRtProcessor#
-
class LiteRtProcessor : public anira::BackendBase#
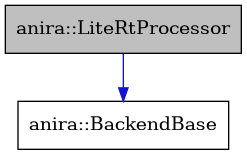
Inheritance diagram for anira::LiteRtProcessor:
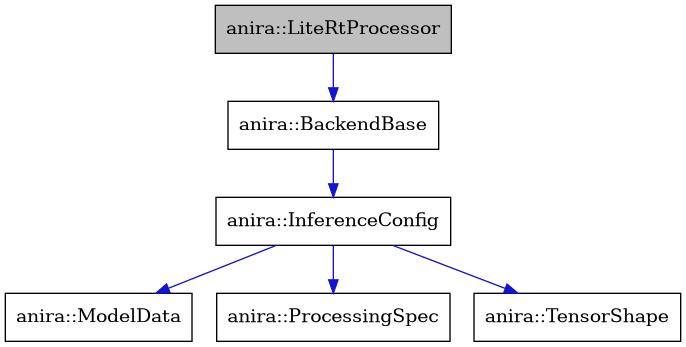
Collaboration diagram for anira::LiteRtProcessor:
LiteRT-based neural network inference processor.
The LiteRtProcessor class provides neural network inference using Google’s LiteRT native C API (the
LiteRt*CompiledModel API). LiteRT is the rebranded successor to TensorFlow Lite and runs the same.tflitemodels; this backend uses LiteRT’s newer native API rather than the legacyTfLite*C API used by TFLiteProcessor.The LiteRT state lives behind the named pimpl
Instance, defined only in LiteRtProcessor.cpp: this header includes no engine header (see BackendBase).See also
Warning
This class is only available when compiled with USE_LITERT defined
Public Functions
-
LiteRtProcessor(InferenceConfig &inference_config)#
Constructs a LiteRT processor with the given inference configuration.
Initializes the LiteRT processor and creates the necessary number of parallel processing instances based on the configuration’s num_parallel_processors setting.
- Parameters:
inference_config – Reference to inference configuration containing model path, tensor shapes, and processing parameters
-
~LiteRtProcessor() override#
Destructor that properly cleans up LiteRT resources.
-
virtual void prepare() override#
Prepares all LiteRT instances for inference operations.
Processes input buffers through the LiteRT model.
- Parameters:
input – Vector of input buffers containing audio samples or parameter data
output – Vector of output buffers to receive processed results
session – Shared pointer to session element providing thread-safe instance access
-
LiteRtProcessor(InferenceConfig &inference_config)#