Class anira::ExecuTorchProcessor#
-
class ExecuTorchProcessor : public anira::BackendBase#
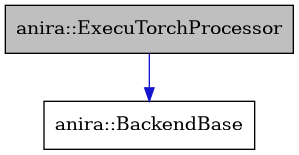
Inheritance diagram for anira::ExecuTorchProcessor:
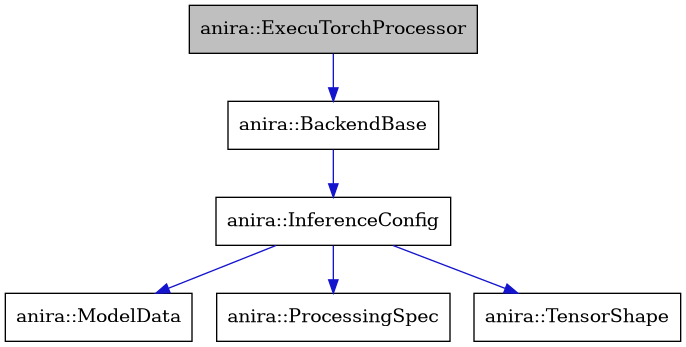
Collaboration diagram for anira::ExecuTorchProcessor:
ExecuTorch-based neural network inference processor.
The ExecuTorchProcessor class provides neural network inference using PyTorch’s ExecuTorch runtime. ExecuTorch is PyTorch’s edge/on-device inference stack: models are exported ahead-of-time with torch.export into a compact .pte program that a small static runtime executes, with CPU execution delegated to XNNPACK. This makes it the PyTorch path on mobile platforms, where LibTorch has no build.
The ExecuTorch state lives behind the named pimpl
Instance, defined only in ExecuTorchProcessor.cpp: this header includes no engine header (see BackendBase). For ExecuTorch that also keeps its vendored copy of the c10 headers from ever shadowing LibTorch’s real c10 in another translation unit.See also
Warning
This class is only available when compiled with USE_EXECUTORCH defined
Public Functions
-
ExecuTorchProcessor(InferenceConfig &inference_config)#
Constructs an ExecuTorch processor with the given inference configuration.
Initializes the ExecuTorch processor and creates the necessary number of parallel processing instances based on the configuration’s num_parallel_processors setting.
- Parameters:
inference_config – Reference to inference configuration containing model path, tensor shapes, and processing parameters
-
~ExecuTorchProcessor() override#
Destructor that properly cleans up ExecuTorch resources.
-
virtual void prepare() override#
Prepares all ExecuTorch instances for inference operations.
Processes input buffers through the ExecuTorch model.
- Parameters:
input – Vector of input buffers containing audio samples or parameter data
output – Vector of output buffers to receive processed results
session – Shared pointer to session element providing thread-safe instance access
-
ExecuTorchProcessor(InferenceConfig &inference_config)#