Class anira::Context#
-
class Context#
Collaboration diagram for anira::Context:
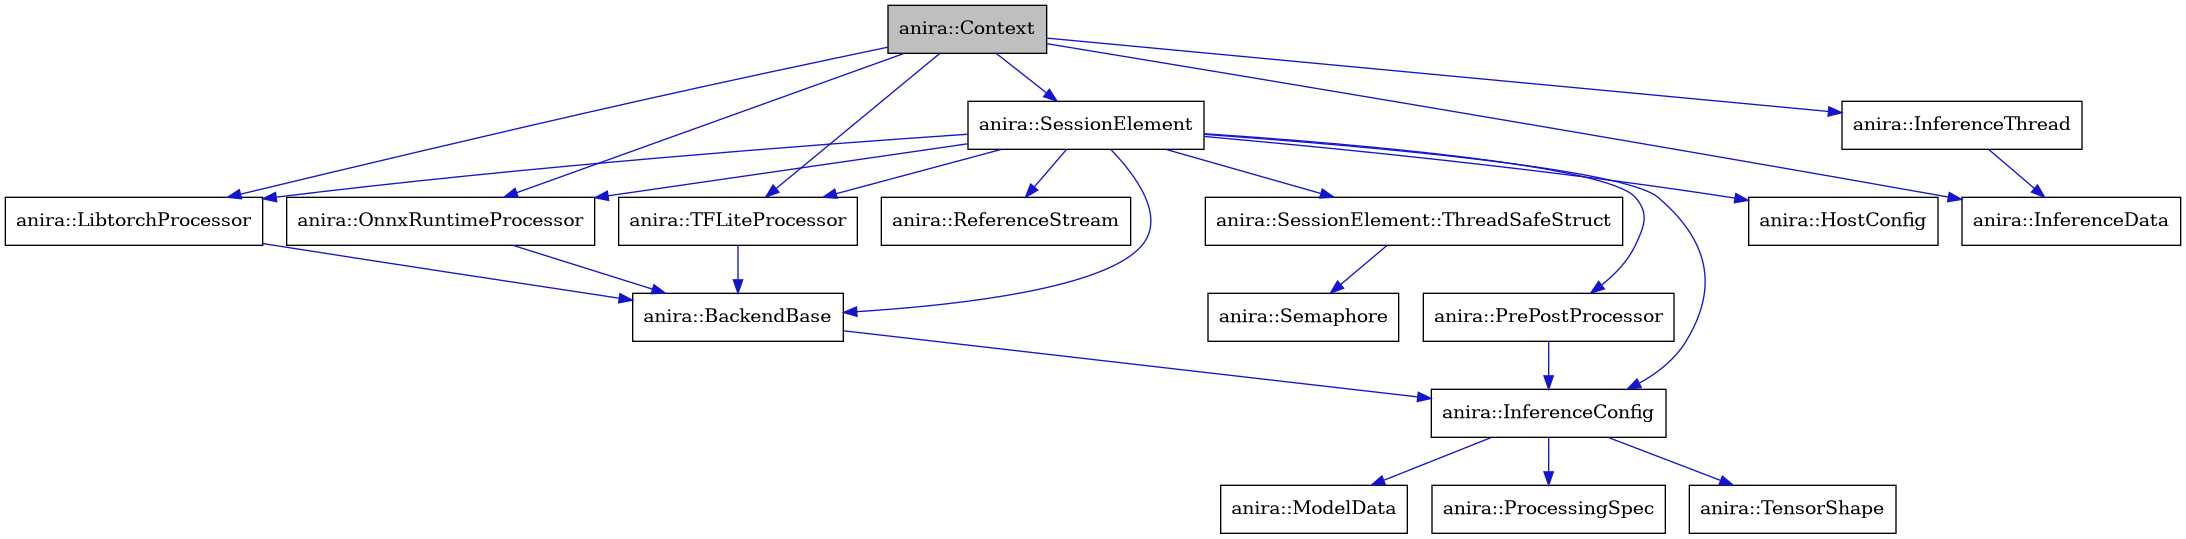
Process-wide inference context: session registry, inference thread pool, backend processor pools and the global inference queue.
The Context coordinates every inference session in a process (or, for a plugin, in the binary that embeds anira): it owns the shared inference thread pool, pools backend processors between sessions with equal configurations, and hands out the global inference queue that the inference threads consume from.
On ELF and Mach-O platforms a library-unload hook additionally calls shutdown() as a backstop for hosts that unload a plugin while an instance is still alive. Windows offers no safe equivalent (nothing that runs at DLL detach may wait for a thread), so a plugin that wants that protection there calls shutdown() from its module-exit entry point (CLAP
deinit, VST3ExitDll) — see the troubleshooting guide.- Lifetime
The context is immortal: its state lives in one heap-allocated core that is created on first use and is never destroyed while the library is loaded. Nothing of it runs during static teardown, so calling into the context is valid at any time, from any thread — including from destructors of static or host-owned objects that happen to run late. The core is reclaimed only when the library is unloaded and nothing is left (see release_core_if_idle()); a plugin that is merely scanned (loaded and unloaded without ever creating a session) allocates nothing.
- Thread pool lifetime
The inference threads exist exactly while sessions exist. This is a rule enforced by the session registry, not a side effect of reference counting: create_session() builds the pool (from that session’s ContextConfig) when it registers the first session, and release_session() stops and joins every pool thread — before it returns, inside the same critical section — when it unregisters the last one. A plugin host may therefore unload the plugin’s shared library as soon as the last InferenceHandler has been destroyed: no thread of anira’s is alive at that point.
- Configuration
The ContextConfig travels with the session: create_session() applies it when the registry is empty and reconciles it against the configuration in effect otherwise (log level: the most verbose requested level wins; wait strategy: the first wins; thread count: the pool only shrinks, and never to zero). Decision and mutation happen in one critical section, so no session can observe a configuration other than the one its pool was built with.
Note
One context per binary. A shared libanira is shared by everything that links it; a plugin that embeds anira statically has its own. (On GCC/Linux, two such plugins used to share one context by accident through unique-symbol binding; they no longer do.)
Public Functions
-
~Context() = default#
Prepares a session for processing with new audio configuration.
Configures the specified session with new audio host settings and optional custom latency values. This method handles buffer allocation, latency calculation, and session state updates, and starts the inference thread pool if it is not running yet.
Note
Thread-safe with respect to other sessions’ lifecycle calls. Not safe against concurrent processing calls on the same session — the host must not process a session it is currently preparing.
- Parameters:
session – Shared pointer to the session to prepare
new_config – New host configuration with audio settings
custom_latency – Optional vector of custom latency values for each tensor
Notifies the context that new data has been submitted for a session.
Signals to the inference system that new audio data is available for processing by the specified session. This triggers the inference pipeline to begin processing the submitted data: an input-driven session (any streamable input) submits one inference per full hop of every streamable input; a generator session (no streamable input) submits one inference per hop of demanded reference-output samples (SessionElement::m_pending_pull_samples).
- Parameters:
session – Shared pointer to the session that has new data available
Collects completed inferences on the push side, as far as they fit.
Post-processes finished inferences in submission order and frees their structs, exactly like the non-waiting new_data_request(), with one extra guard: a result is only placed while every streamable receive ring can take it (SessionElement::receive_rings_have_room()). Otherwise the result stays in its struct and false is returned — the host is producing streamed output it never pops. Called from InferenceManager::push_data() so that push-only hosts (an analyser reading its non-streamable outputs) never exhaust the struct pool. Non-blocking for both completion signals; in non-real-time mode it waits for the oldest in-flight inference like every other collection point.
- Parameters:
session – Shared pointer to the session to collect for
- Returns:
False if a completed result could not be placed because a receive ring is full, true otherwise
Requests new data processing for a session.
Requests that the inference system process data for the specified session. This is used for scheduling and managing inference operations. The request is processed immediately. Completed results are placed only while the streamable receive rings have room for them (see collect_completed()), so unread output is never overwritten.
Note
If the session is in non-real-time mode (see InferenceManager::set_non_realtime()), this blocks until the pending inference completes instead of returning immediately.
- Parameters:
session – Shared pointer to the session requesting data processing
Requests new data processing for a session at a specific time.
Requests that the inference system process data for the specified session, but waits for the data until the given time point before processing. Completed results are placed only while the streamable receive rings have room for them (see collect_completed()).
Note
If the session is in non-real-time mode (see InferenceManager::set_non_realtime()), this blocks until the pending inference completes instead of honoring wait_until.
- Parameters:
session – Shared pointer to the session requesting data processing
wait_until – Time point at which to begin processing the data request
Wait-free reset of a session, safe on the session’s driving (audio) thread.
NEVER blocks the caller on in-flight inferences: it bumps the session generation (invalidating every already-dispatched inference) and then calls SessionElement::clear(). Stale inferences complete on their worker threads, have their results discarded (new_data_request() generation guard), and their structs reclaimed lazily by reclaim_stale_structs() from new_data_submitted(). The observable output is identical to the former blocking reset, which also discarded the in-flight result — it merely waited first so it could safely wipe the struct memory.
Supported for all session types. For a session-exclusive (stateful) session, the pending-dispatch chain is reconciled without waiting: pending entries are returned to the free pool by the gate-holder (this call when the gate is free, otherwise the worker at its next task boundary — see SessionElement::try_acquire_next_dispatch). Nothing is ever enqueued from this call, so it performs no queue, semaphore, or logging syscalls.
Must be called from the session’s single driving thread (the thread that runs process()/push_data()/pop_data()), or with no such call concurrent.
- Parameters:
session – Shared pointer to the session to reset
Public Static Functions
-
static Context &get_instance()#
Returns the process-wide context.
The context is immortal and always valid to call (see the class description), so the returned reference never dangles.
- Returns:
Reference to the context
-
static std::shared_ptr<Context> get_instance(const ContextConfig &context_config)#
Deprecated: returns the context and stages a configuration for the deprecated three-argument create_session()
Kept for one minor release so existing code compiles unchanged. The returned shared_ptr is non-owning (the context is never destroyed). The configuration is applied when the next session is created via the three-argument create_session() — pass it to the four-argument create_session() directly instead.
- Deprecated:
Use get_instance() and create_session(PrePostProcessor&,InferenceConfig&, BackendBase*, const ContextConfig&).
- Parameters:
context_config – Configuration to apply with the next session
- Returns:
Non-owning shared pointer to the context
-
static std::shared_ptr<SessionElement> create_session(PrePostProcessor &pp_processor, InferenceConfig &inference_config, BackendBase *custom_processor, const ContextConfig &context_config)#
Creates and registers a new inference session.
Applies or reconciles the given ContextConfig (see the class description), builds the session with its preprocessing/postprocessing pipeline, inference configuration and optional custom backend, and registers it. When this is the first session, the inference thread pool is built from
context_config(its threads are started by prepare_session()).Registration is the last step: if anything before it throws (typically a backend that cannot load the model), the registry, the thread pool and the configuration are left exactly as they were and any backend processor created for the failed session is released again. Nothing leaks.
Note
Thread-safe: may be called from any non-realtime thread, including concurrently with other sessions’ lifecycle calls.
- Parameters:
pp_processor – Reference to the preprocessing/postprocessing pipeline
inference_config – Reference to the inference configuration
custom_processor – Pointer to a custom backend processor (nullptr for default backends)
context_config – Configuration of the context as requested by this session
- Returns:
Shared pointer to the newly created session
-
static std::shared_ptr<SessionElement> create_session(PrePostProcessor &pp_processor, InferenceConfig &inference_config, BackendBase *custom_processor)#
Deprecated: creates a session with the configuration staged by the deprecated get_instance(const ContextConfig&) (or the one in effect, or a default one)
- Deprecated:
Pass the ContextConfig to create_session() directly.
Releases an inference session and its resources.
Drains the session’s in-flight inferences, unregisters it and releases its backend processors. When this was the last session, the inference thread pool is stopped and joined before this function returns, in the same critical section as the unregistration — after the last InferenceHandler is destroyed no anira thread exists.
Note
Thread-safe: may be called from any non-realtime thread, including concurrently with other sessions’ lifecycle calls.
- Parameters:
session – Shared pointer to the session to release
-
static void shutdown()#
Stops and joins the inference thread pool, regardless of registered sessions.
Idempotent and cheap when there is nothing to do (in particular it never creates the context: a binary that never created a session pays nothing). Registered sessions stay registered; the pool is rebuilt by the next create_session() into an empty registry.
With the default lifecycle the pool is already gone once the last session was released, so this is a backstop for hosts that unload a plugin’s library while an instance is still alive. On ELF/Mach-O it is called automatically from a library-unload hook; on Windows nothing that runs at DLL detach may wait for a thread, so call it from your module-exit entry point (CLAP
deinit, VST3ExitDll) — those run before the host unloads the library and outside the loader lock.Note
Not real-time safe (joins threads). Logs an error if sessions are still registered — a host that unloads live instances is a host bug; the sessions’ memory is leaked, no thread is.
-
static size_t drain_log()#
Forwards the records anira’s real-time paths have logged to the log sinks.
The audio thread and the inference threads log into a lock-free queue owned by the context (see LogConfig). With LogDrain::Manual the host calls this periodically (e.g. from a UI timer); with LogDrain::Thread the context’s own thread does it and this call is just an extra flush. Returns the number of records delivered. Not real-time safe: the sinks (platform log, file, the host’s callback) run on the calling thread.
-
static bool release_core_if_idle()#
Frees the context core if nothing uses it.
Deletes the core when no session is registered, no pool thread exists and no user-managed inference thread is active (see make_inference_thread()). The next call into the context creates a fresh core. Called from the library-unload hook after shutdown(), so that a plugin’s load/unload cycle leaves no memory behind.
Warning
Only safe when no other thread can call into anira concurrently (which is the case at library unload). Never blocks: if the lifecycle lock is held by someone, nothing is freed.
- Returns:
True if the core was freed, false if it did not exist or is in use
-
static bool has_core()#
Whether the context core currently exists.
True from the first call that needs the core (typically create_session()) until release_core_if_idle() frees it. Diagnostic; used by the tests.
- Returns:
True if the core is allocated
-
static int get_num_sessions()#
Gets the number of registered inference sessions.
- Returns:
Number of currently registered sessions
-
static std::vector<std::shared_ptr<SessionElement>> get_sessions()#
Gets a snapshot of all registered sessions.
Returns a copy of the registry, taken under the lifecycle lock. Primarily used for internal management and debugging.
- Returns:
Vector of the registered sessions’ shared pointers
-
static InferenceQueue &get_static_inference_queue()#
Get a reference to the global inference queue.
Returns a reference to the global concurrent queue used for inference requests. This is used to construct InferenceThreads (user-managed or WASM worker-driven) that consume from the global queue; dequeueing is non-tokenized and allocation-free.
The queue lives in the immortal context core, so the reference stays valid for as long as the library is loaded — in particular after all sessions were released.
- Returns:
Reference to the global inference queue
-
static std::unique_ptr<InferenceThread> make_inference_thread()#
Factory for a user-owned InferenceThread bound to the global inference queue.
Returns a new InferenceThread whose lifecycle is fully managed by the caller. The thread is not started automatically — call start() on the returned object to begin processing. The caller must also call stop() (or simply destroy the object) before program exit — and, for a plugin, before its library is unloaded: the unload hook joins only the context’s own pool.
This is purely additive: the auto-managed thread pool sized via ContextConfig::m_num_threads continues to work unchanged. Users who want full control over threading typically construct their sessions with ContextConfig(0) so that no auto-pool threads exist, then create and manage threads themselves via this factory.
The returned thread references the global inference queue, which lives in the immortal context core — so the thread remains valid even after all sessions have been released.
- Returns:
Unique pointer to a new user-owned InferenceThread.
-
static unsigned int get_num_inference_threads()#
Number of inference threads currently active in the process.
Native: threads currently executing their processing loop — the auto-managed pool once started plus any user-created threads. WebAssembly: externally driven threads that have been started and not yet stopped (i.e. the inference workers currently spun up; exposed to JavaScript as AniraWeb.getNumInferenceThreads()). See InferenceThread::get_num_active_threads() for the exact semantics.
- Returns:
Number of active inference threads.
-
static bool has_inference_threads()#
Whether any inference threads exist that could satisfy blocking (non-real-time) waits.
True when the auto-managed pool is non-empty (native; its threads are started in prepare_session()) or at least one externally driven thread is active (user-created on native, JS-driven on WebAssembly, where the pool is always empty). Used to gate InferenceManager::set_non_realtime(true), whose unbounded waits would otherwise never complete.
- Returns:
True if at least one inference thread is configured or active.