Class anira::SessionElement#
-
class SessionElement#
Collaboration diagram for anira::SessionElement:
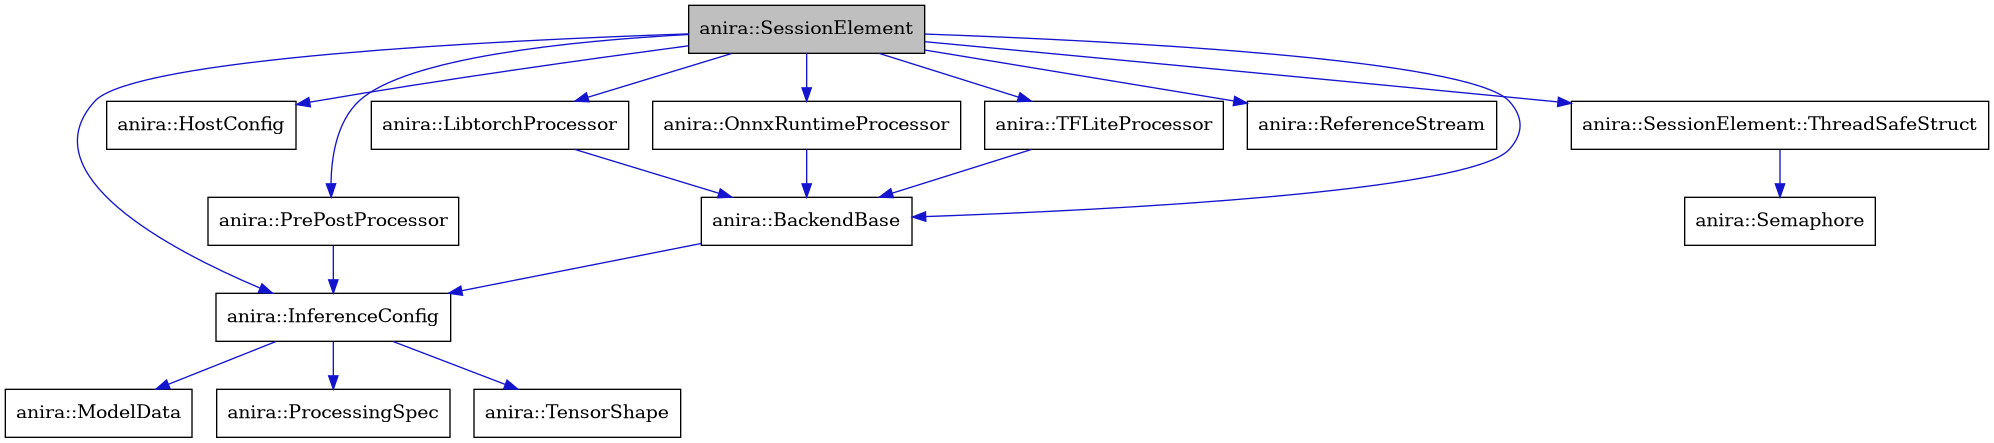
Core session management class for individual inference instances.
The SessionElement class represents a single inference session, managing all resources and state required for neural network inference processing. Each session is independent and can have different configurations, backends, and processing parameters while sharing the global inference thread pool and context.
Key responsibilities:
Managing input/output ring buffers for continuous audio streaming
Coordinating with backend processors (LibTorch, ONNX, TensorFlow Lite)
Latency compensation (the latency itself is computed by LatencyCalculator)
Managing thread-safe data structures for multi-threaded processing
Session lifecycle management and resource cleanup
The session uses ring buffers for efficient audio streaming and maintains multiple thread-safe structures to enable concurrent processing without blocking the audio thread. Latency, the number of those structures and the ring sizes are computed in closed form by LatencyCalculator from the model characteristics and the host audio configuration.
Note
Each session has a unique ID and maintains its own processing state while participating in the global inference scheduling system.
Public Functions
-
SessionElement(int new_session_id, PrePostProcessor &pp_processor, InferenceConfig &inference_config, moodycamel::ProducerToken &&producer_token)#
Constructor that initializes a session with specified components.
Creates a new session element with a unique ID and associates it with the provided preprocessing/postprocessing pipeline and inference configuration. The session is not fully initialized until prepare() is called.
- Parameters:
new_session_id – Unique identifier for this session
pp_processor – Reference to the preprocessing/postprocessing pipeline
inference_config – Reference to the inference configuration containing model settings
producer_token – Producer token bound to the global inference queue, moved into the session (see m_producer_token)
-
void clear()#
Wait-free clear of the session’s audio-thread-owned state.
Resets the audio-thread-owned state (send/receive ring buffers, timestamp bookkeeping, latency re-seed) and any ThreadSafeStruct that is currently free, but never touches a struct that a worker still holds in flight (m_free == false). It therefore does NOT require Context::drain_inference_queue() as a precondition and never blocks the caller.
Correctness is provided by the session generation (see m_generation): the caller (Context::reset_session) bumps the generation first, which makes every already-dispatched inference “stale” — its result is ignored by Context::new_data_request() and its struct is reclaimed by Context::reclaim_stale_structs() (run from new_data_submitted()) once the worker publishes completion. Valid for all session types; the stateful dispatch chain is reconciled separately (see discard_pending_dispatches() and the generation filter in try_acquire_next_dispatch()).
-
void prepare(const HostConfig &spec, std::vector<long> custom_latency = {})#
Prepares the session for processing with specified audio configuration.
Initializes all buffers, calculates latencies, and configures the session for processing with the provided host audio configuration. This method must be called before the session can process audio data.
The host configuration’s reference stream (HostConfig::resolve_reference) is resolved here, once, and stored in m_reference / m_input_driven for the real-time path.
- Parameters:
spec – Host configuration containing sample rate, buffer size, and audio settings
custom_latency – Optional vector of custom latency values for each tensor (empty for automatic calculation); entries for non-streamable outputs are ignored, their latency is always 0
- Throws:
std::invalid_argument – if the host config’s reference stream cannot be resolved (explicit reference out of range or not streamable, or no streamable tensor at all)
Template method for setting backend processors.
Assigns a specific backend processor to this session. This template method works with any supported backend type (LibTorch, ONNX, TensorFlow Lite).
- Template Parameters:
T – Backend processor type
- Parameters:
processor – Shared pointer to the backend processor to assign
-
bool receive_rings_have_room()#
Whether every streamable receive ring can take one more inference result.
True if each streamable output’s ring buffer has at least postprocess_output_size free samples (trivially true when no output is streamable). Used by the push-side collection in Context::collect_completed() so that a completed result is only post-processed when it fits, and unread output is never overwritten.
- Returns:
True if a completed inference can be post-processed without overflowing a ring
Queue a prepared stateful task awaiting dispatch (called in submission order on the session’s driving thread; allocation-free). If the pending queue rejects the task — which the capacity bound makes unreachable — it is completed with zeroed output instead.
-
std::shared_ptr<ThreadSafeStruct> try_acquire_next_dispatch()#
Claim the next stateful task to dispatch, or nullptr if one is already in flight or none are pending. Pending entries whose dispatch generation is stale (a wait-free reset bumped m_generation after they were prepared) are returned straight to the free pool and skipped: they were never handed to a worker, so the gate-holder owns them exclusively. The returned struct carries the gate token in m_dispatch_epoch, which the holder must pass back to release_dispatch().
-
void release_dispatch(uint64_t token)#
Mark the in-flight stateful task finished, allowing the next to be dispatched. Epoch-checked: a token from before a force_reset_dispatch_chain() fails silently.
-
void discard_pending_dispatches()#
Wait-free reset kick for the stateful dispatch chain (driving thread only, called right after the generation bump): if no task is in flight, acquires the gate, returns every pending entry to the free pool (all are stale — same driving thread, so nothing fresh can have been prepared since the bump) and releases. Never enqueues, so the reset path stays free of queue/semaphore/logging syscalls. If a task is in flight, does nothing: the worker filters the stale prefix at its next task boundary.
-
void force_reset_dispatch_chain()#
Quiescent-only (a drain has run; no task of this session is queued or running, though a laggard worker may still transiently hold the gate while filtering stale entries): waits out any transient gate holder, opens a new dispatch epoch (so any release carrying a pre-reset token is inert, whatever the interleaving), then flushes the pending queue. Blocking (sleeps in 50us steps while the gate is held) — called only from prepare(), never from a real-time path.
Complete a task without running inference: zero its output tensors and signal completion. Used when the global queue rejects a task, so the dropped inference still yields (silent) output at its correct stream position and the struct is freed normally.
Public Members
-
std::vector<RingBuffer> m_send_buffer#
Ring buffers for input data streaming to inference.
-
std::vector<RingBuffer> m_receive_buffer#
Ring buffers for output data streaming from inference
-
std::vector<std::shared_ptr<ThreadSafeStruct>> m_inference_queue#
Pool of thread-safe structures for concurrent processing
-
std::atomic<InferenceBackend> m_current_backend = {CUSTOM}#
Currently active inference backend for this session. Initialized by Context::create_session to the first configured model’s available backend (CUSTOM when a custom processor was provided or nothing matches).
-
unsigned long m_current_queue = 0#
Current position in the inference queue.
-
std::vector<unsigned long> m_time_stamps#
Vector of timestamps for performance monitoring.
-
size_t m_pending_pull_samples = 0#
Generator sessions only (!m_input_driven): samples of the reference output the driving thread has demanded that no submitted inference covers yet. Plain field, written and read only on the session’s driving thread (like m_time_stamps).
-
const int m_session_id#
Unique identifier for this session (immutable)
-
std::atomic<bool> m_initialized = {false}#
Atomic flag indicating if the session is fully initialized
-
std::atomic<int> m_active_inferences = {0}#
Atomic counter of currently active inference operations
-
std::atomic<uint64_t> m_generation = {0}#
-
moodycamel::ProducerToken m_producer_token#
Per-session producer token for the global inference queue
-
std::atomic<uint64_t> m_stateful_dispatch_gate = {0}#
{epoch, busy} dispatch gate; busy while a stateful task of this session is queued or running
-
moodycamel::ConcurrentQueue<std::shared_ptr<ThreadSafeStruct>> m_dispatch_pending#
Prepared-but-not-yet-dispatched stateful tasks, in submission order
-
moodycamel::ProducerToken m_dispatch_producer_token#
Explicit producer for m_dispatch_pending
-
PrePostProcessor &m_pp_processor#
Reference to the preprocessing/postprocessing pipeline.
-
InferenceConfig &m_inference_config#
Reference to the inference configuration.
-
BackendBase m_default_processor#
Default backend processor instance.
-
BackendBase *m_custom_processor#
Pointer to custom backend processor (if provided)
-
std::atomic<bool> m_is_non_real_time = {false}#
True forces new_data_request() to block until each pending inference completes, ignoring blocking_ratio and any deadline, trading real-time safety for complete, deterministic output (see Context::new_data_request).
-
std::vector<unsigned int> m_latency#
Calculated latency values for each output tensor in samples, index-aligned with the output tensor list; 0 for non-streamable outputs
-
ReferenceStream m_reference#
Reference stream resolved once in prepare(); read on the real-time path, never re-resolved there
-
bool m_input_driven = true#
True if any input tensor is streamable: inference is triggered by arriving input samples. False for a generator (no streamable input), whose inference is triggered by output demand (see m_pending_pull_samples).
-
size_t m_num_structs = 0#
Number of allocated thread-safe structures: twice the steady-state bound of LatencyCalculator::get_num_structs(), so that the inferences a wait-free reset() strands until their workers finish never starve the fresh schedule (for testing access)
-
std::vector<size_t> m_send_buffer_size#
Calculated send buffer sizes (for testing access)
-
std::vector<size_t> m_receive_buffer_size#
Calculated receive buffer sizes (for testing access)
-
std::shared_ptr<LibtorchProcessor> m_libtorch_processor = nullptr#
Shared pointer to LibTorch backend processor (if available)
-
std::shared_ptr<OnnxRuntimeProcessor> m_onnx_processor = nullptr#
Shared pointer to ONNX Runtime backend processor (if available)
-
std::shared_ptr<TFLiteProcessor> m_tflite_processor = nullptr#
Shared pointer to TensorFlow Lite backend processor (if available)
-
std::shared_ptr<LiteRtProcessor> m_litert_processor = nullptr#
Shared pointer to LiteRT backend processor (if available)
-
std::shared_ptr<ExecuTorchProcessor> m_executorch_processor = nullptr#
Shared pointer to ExecuTorch backend processor (if available)
Public Static Attributes
-
static constexpr uint64_t k_dispatch_busy = 1#
-
struct ThreadSafeStruct#
Collaboration diagram for anira::SessionElement::ThreadSafeStruct:

Thread-safe data structure for concurrent inference processing.
This nested structure provides thread-safe coordination between the audio thread and inference threads. Each structure can hold one inference request and includes synchronization primitives to ensure safe concurrent access.
The structure uses atomic operations and semaphores to coordinate:
Availability checking (m_free)
Completion notification (m_done_semaphore, m_done_atomic)
Data integrity during concurrent access
Timestamping for latency tracking
Public Functions
-
ThreadSafeStruct(const std::vector<size_t> &tensor_input_size, const std::vector<size_t> &tensor_output_size)#
Constructor that initializes thread-safe structure with tensor dimensions.
Creates buffers for input and output tensors with the specified sizes and initializes synchronization primitives.
- Parameters:
tensor_input_size – Vector of input tensor sizes
tensor_output_size – Vector of output tensor sizes
Public Members
-
std::atomic<bool> m_free = {true}#
Atomic flag indicating if this structure is available for use
-
std::atomic<bool> m_done_atomic = {false}#
Atomic flag for non-blocking completion checking
-
unsigned long m_time_stamp#
Timestamp for latency tracking and debugging. Written only on the session’s driving (audio) thread — keep it that way; it is a plain field.
-
uint64_t m_dispatch_generation = {0}#
-
uint64_t m_dispatch_epoch = {0}#